

How to Become a Big Data Expert?
 Aman Singh
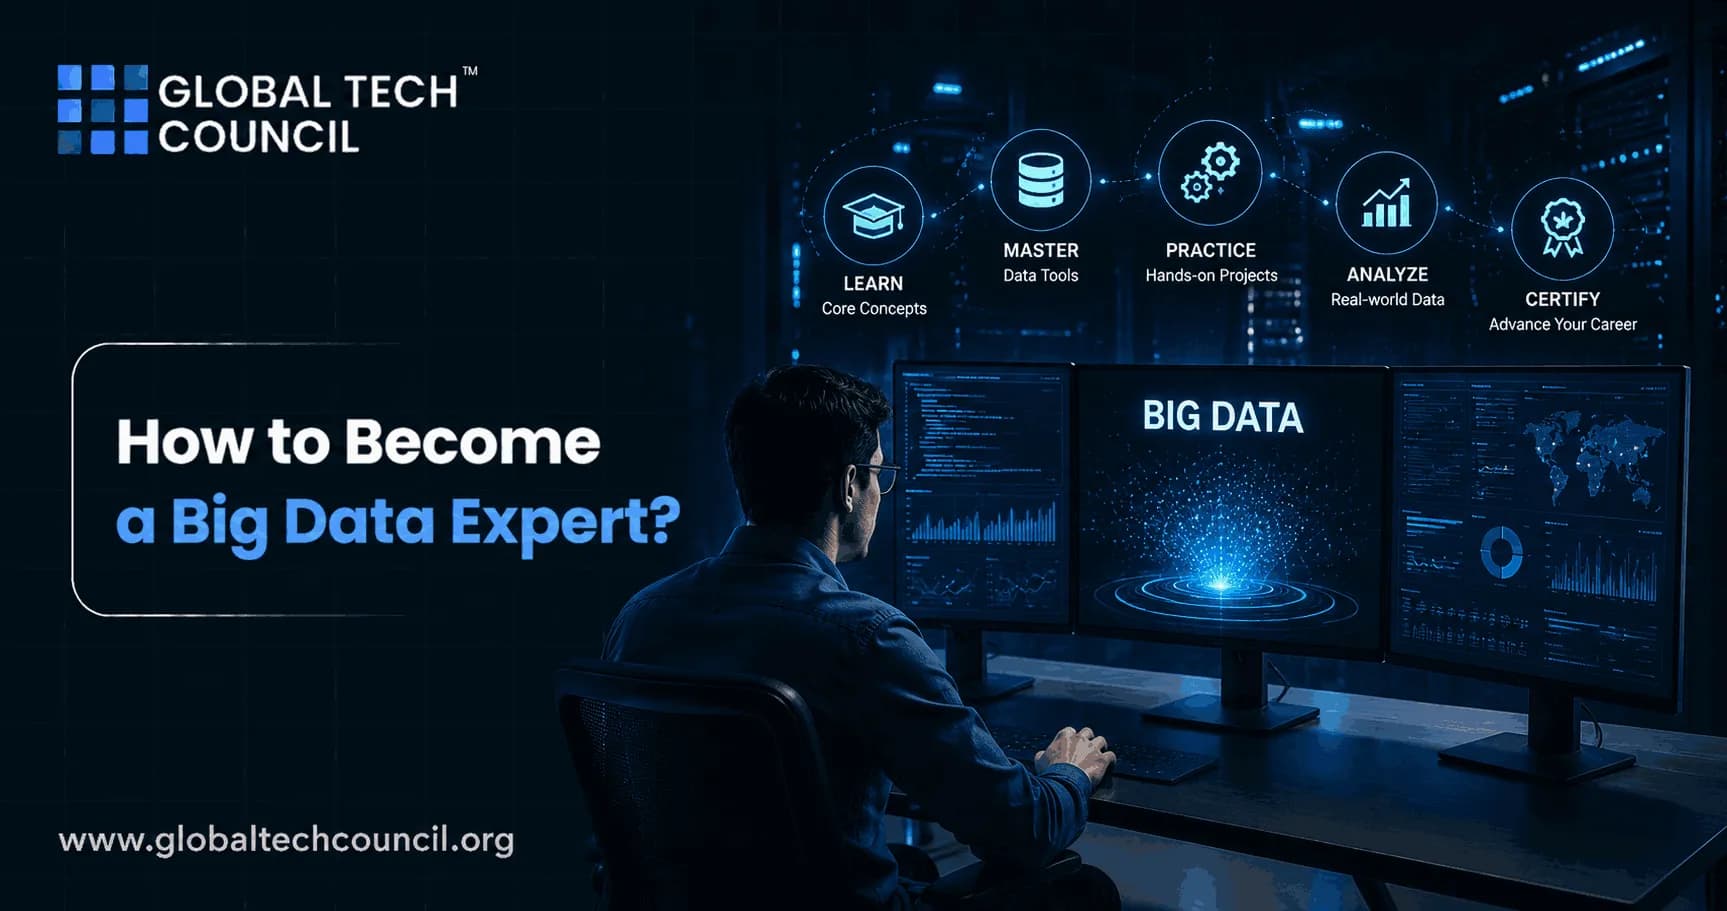
Organizations today are generating more data than they know what to do with, and the professionals who can actually build the systems to make sense of it remain in seriously short supply. Global spending on data engineering services is projected to reach roughly $105 billion in 2026, and the World Economic Forum has projected demand for big data specialists to grow by more than 100 percent between 2025 and 2030. For anyone considering this path, the opportunity has rarely looked stronger, and many people starting this journey pursue a Certified Big Data Expert credential to build structured, verifiable expertise rather than piecing together scattered tutorials and outdated advice.
In this article, we will walk through what Big Data actually means, the core skills and technologies required, current 2026 salary data, and a practical roadmap for building genuine expertise in this field.
Understanding the Basics of Big Data
Big Data refers to the massive volume of structured and unstructured data organizations generate daily, arriving from sources like social media, connected sensors, online transactions, and countless other digital touchpoints. This data is typically defined by three core characteristics, often called the three Vs. Volume refers to the sheer scale of data involved, often ranging from terabytes into petabytes and beyond, far exceeding what a traditional database can efficiently handle. Velocity refers to the speed at which data is generated and needs to be processed, frequently in real time. Variety refers to the diversity of data types involved, spanning text, images, video, and more, each requiring different handling and analysis approaches.
Several foundational concepts sit underneath this definition. Data processing covers the work of collecting, cleaning, and transforming raw data into a genuinely usable format. Data mining involves discovering meaningful patterns and trends within a dataset through techniques like clustering and classification. Data warehousing refers to the centralized repositories that store data from multiple sources for efficient retrieval and analysis. And understanding the distinction between structured data, which is organized and easy to query, and unstructured data, like free text or images, remains fundamental to nearly everything that follows.
Programming Languages Every Big Data Professional Needs
Proficiency in the right programming languages remains one of the clearest differentiators between someone who understands Big Data conceptually and someone who can actually work with it. Python continues to dominate the field in 2026, prized for its versatility and its extensive ecosystem of data libraries like Pandas and NumPy that simplify manipulation and analysis. R remains valuable for statistical computing and visualization work, particularly through libraries like ggplot2. And Java still underpins many core Big Data frameworks, including Hadoop, making it genuinely useful even though it sees less direct use in day to day data analysis than Python.
Building genuine fluency across these languages, along with the broader technical stack surrounding them, is exactly what structured Programming Languages Certifications are designed to support, giving learners a verified, structured path through the specific languages employers are actually hiring for rather than a scattered, self directed approach.
Mastering Statistics and Mathematics
Data analysis is inherently mathematical, and meaningful interpretation of any dataset depends on a solid statistical foundation. Descriptive statistics, covering measures like mean, median, and standard deviation, provide the basic vocabulary for summarizing data. Probability distributions, hypothesis testing, and regression analysis round out the core statistical toolkit needed to move from raw numbers to genuinely defensible conclusions. On the mathematics side, algebra, calculus, and discrete mathematics, including graph theory, continue to underpin many of the algorithms and optimization techniques used throughout the field.
Databases, SQL, and Modern Data Infrastructure
Big Data is often stored across a mix of relational database systems, including MySQL, PostgreSQL, and Microsoft SQL Server, alongside NoSQL databases like MongoDB and Cassandra built specifically for unstructured data at scale. SQL remains the essential language for querying and retrieving this data, and hands on practice with real databases continues to be one of the fastest ways to build genuine, applicable skill in this area.
Big Data Technologies: What's Actually in Demand in 2026
Hadoop, built around its distributed file system and MapReduce processing model, remains a foundational technology in the field, though its role has evolved considerably as newer tools have matured around it. Apache Spark has become the dominant processing engine for most modern Big Data work, valued for its in-memory processing speed and considerably more accessible API compared to older MapReduce jobs.
Beyond these two established pillars, 2026's job market data points to a clear set of tools now considered essential rather than optional. Real time streaming technologies like Kafka and Flink have become genuine differentiators, since engineers who can run production streaming pipelines are treated as a fundamentally different, more valuable talent pool than those with batch processing experience alone. Cloud platforms, particularly AWS, alongside modern data warehousing tools like Snowflake and increasingly Databricks, now appear as requirements in a meaningful share of job postings, reflecting how thoroughly cloud native architecture has replaced on premises infrastructure across most organizations.
What Big Data Professionals Actually Earn in 2026
Compensation data for 2026 shows a genuinely strong market, though figures vary considerably depending on the specific source, role, and location. Glassdoor data from May 2026 places the average Big Data Engineer salary at approximately $144,000 annually in the United States, with a typical range between roughly $115,000 and $184,000, and top earners reaching past $227,000. Robert Half's 2026 salary guide reports a similar range, between $127,000 and $180,750. Entry level roles typically start between $85,000 and $100,000, while senior specialists at major technology and finance companies routinely clear $180,000 to $220,000 in base pay, with total compensation at companies like Google and Meta reportedly reaching between roughly $200,000 and $345,000 once bonuses and equity are included.
Location continues to matter significantly, though hybrid work has narrowed some of the traditional geographic gaps. San Francisco remains among the highest paying markets, with salaries often ranging from $148,000 to $186,000, while cities like Houston have emerged as genuinely competitive hubs, driven partly by energy sector companies building out massive data platforms for AI, predictive maintenance, and regulatory reporting.
Gaining Domain Expertise
Specializing within a specific industry consistently makes Big Data expertise more valuable and harder to replace. Healthcare specialists work with electronic health records and healthcare analytics. Finance specialists focus on market trends, transaction data, and risk analysis. E-commerce specialists analyze customer behavior and build recommendation systems. Choosing a domain and building genuine depth there, rather than remaining a pure generalist, has become an increasingly clear differentiator in a market where demand for skilled talent continues to outpace supply.
Building Practical, Hands On Experience
Formal knowledge only carries a Big Data career so far without real, demonstrable project experience. Building customer segmentation models, predictive analytics systems, sentiment analysis pipelines, and recommendation engines all give learners genuine, portfolio ready work to point to. Participating in hackathons and data science competitions adds further practical experience while also building the kind of professional network that often leads directly to real opportunities.
Building Technical Foundations Early
Interest in fields like Big Data and computer science often takes root long before someone enters a formal career path, and cultivating this kind of curiosity at a younger age can make a genuine difference later on.
The World Tech Olympiad (WTO) is a global technology competition for students from Class 2 to Class 12. Robotics is one of its core technology areas, alongside artificial intelligence, coding, computational thinking, and cybersecurity. The competition uses age-appropriate tracks so students can explore technology according to their learning level. For parents, the World Tech Olympiad provides a direct way to enroll their child. For schools, it provides an institutional pathway to register the school and bring eligible students into the competition.
Introducing students to computational thinking and structured problem solving at this stage builds a genuine foundation for the kind of technical fluency that fields like Big Data increasingly demand.
Formal Education and Certification
A degree in data science, computer science, or a related field remains a strong foundation, and advanced degrees can open doors to deeper research and specialized roles. Certification adds a genuinely useful, faster path to demonstrating real, verified competency, particularly for career changers moving into the field from an adjacent technical background. Beyond a single Big Data credential, many learners also pursue a broader Deep Tech Certification, building well rounded technical literacy across adjacent fields like cloud infrastructure and AI that make core Big Data skills significantly more applicable in real, modern production environments.
Developing Essential Soft Skills
Technical mastery alone rarely tells the full story employers and stakeholders need to hear. Strong communication skills, including the ability to translate complex findings into clear, accessible language for non technical audiences, remain genuinely essential. Data storytelling and visualization tools like Tableau or Power BI help turn raw analysis into insight decision makers can actually act on. Problem solving ability, the capacity to break down genuinely complex issues into manageable, solvable pieces, continues to separate strong Big Data professionals from those who can only operate within a narrow, predefined scope.
Given how much a Big Data career increasingly depends on communicating value clearly, whether pitching a project internally or explaining insights to a client, many professionals also pursue a Marketing Certification, strengthening their ability to present technical work persuasively to audiences who may not share the same background.
Staying Ethical and Building Your Network
Respecting data privacy and understanding regulations like GDPR remain non negotiable parts of working responsibly with Big Data, particularly as scrutiny around data ethics, bias, and fairness continues to intensify. Building a genuine professional network, through industry events, conferences, and mentorship relationships, continues to open doors that technical skill alone often cannot.
Final Thoughts
Becoming a Big Data expert in 2026 means building real fluency across programming, statistics, and modern cloud based technologies, while increasingly specializing in a specific domain or technical niche that commands a genuine premium in today's market. With demand for skilled Big Data professionals projected to more than double by 2030 and salaries continuing to climb across nearly every experience level, this remains one of the most consistently rewarding technical fields a motivated learner can enter.
The path does not require mastering everything at once. It requires steady, deliberate progress, sometimes starting as early as a school level technology competition, and building consistently toward the kind of verified, practical expertise the current market continues to reward at every stage of a career.
FAQs
1. How Can You Become a Big Data Expert?
To become a Big Data expert, develop strong foundations in programming, SQL, databases, data modeling, distributed computing, cloud platforms, and data engineering. Then learn technologies used to process large-scale datasets, such as Apache Spark and the broader Hadoop ecosystem. A practical roadmap is Python → SQL → Databases → Data Modeling → Distributed Systems → Spark → Data Pipelines → Cloud → Projects → Specialization. Expertise comes from building systems that work reliably at scale, not merely learning enough technology names to make a résumé intimidating.
2. What Does a Big Data Expert Do?
A Big Data expert works with large, complex, or rapidly generated datasets that conventional processing approaches may struggle to handle efficiently. Responsibilities can include designing data architectures, building pipelines, processing batch and streaming data, maintaining data lakes or warehouses, improving data quality, and supporting analytics and AI applications. Depending on specialization, professionals may work as data engineers, Big Data developers, architects, analytics engineers, or platform engineers.
3. What Skills Do You Need to Become a Big Data Expert?
Important Big Data skills include Python, SQL, databases, data modeling, ETL and ELT, distributed computing, Apache Spark, data warehouses, data lakes, cloud computing, workflow orchestration, streaming, and data governance. Professionals should also understand Linux, Git, APIs, containers, security, and performance optimization. Modern Big Data roles increasingly overlap with AI infrastructure because machine learning and generative AI systems require dependable, well-governed data pipelines.
4. Is Python Important for Big Data?
Yes. Python is widely used for data processing, automation, analytics, pipeline development, and integration with data platforms. Beginners should understand Python fundamentals, functions, classes, data structures, file handling, APIs, and error handling before progressing to distributed processing. Python also provides a useful bridge between data engineering, analytics, machine learning, and AI, making it one of the more practical languages to learn for a Big Data career.
5. How Important Is SQL for a Big Data Career?
SQL is one of the most important skills for working with data. Big Data professionals use SQL to query, transform, aggregate, validate, and analyze information across databases, warehouses, and distributed query systems. Learners should understand joins, aggregations, subqueries, common table expressions, window functions, indexing concepts, query execution, and optimization. Anyone attempting to become a data expert while avoiding SQL has selected an unusually creative form of professional self-sabotage.
6. What Is Big Data and Why Is It Important?
Big Data describes datasets and data-processing requirements characterized by factors such as large volume, high velocity, substantial variety, and complexity. Organizations use large-scale data systems to support analytics, personalization, fraud detection, forecasting, operational intelligence, machine learning, and AI. The objective is not simply storing enormous quantities of information. It is transforming data into reliable, accessible information that can support decisions and applications.
7. What Are the 5 Vs of Big Data?
The five commonly discussed characteristics are Volume, Velocity, Variety, Veracity, and Value. Volume concerns the amount of data, velocity concerns how quickly it arrives and must be processed, and variety describes different formats and sources. Veracity concerns quality and reliability, while value asks whether the data produces useful outcomes. That final V is rather important, since accumulating petabytes of unusable information is technically impressive but commercially less thrilling.
8. What Is Apache Hadoop and Should Big Data Professionals Learn It?
Apache Hadoop is an open-source framework and ecosystem associated with distributed storage and processing of large datasets across clusters of computers. Understanding Hadoop concepts such as HDFS and distributed processing remains useful for learning how large-scale data systems evolved. However, modern professionals should broaden their skills beyond Hadoop and learn Spark, cloud-native data services, modern warehouses, lakehouses, and streaming architectures.
9. What Is Apache Spark and Why Should You Learn It?
Apache Spark is a multi-language engine for data engineering, data science, and machine learning on single machines or clusters. It supports large-scale processing and is commonly used for ETL, analytics, streaming, and machine-learning workloads. Big Data learners should understand Spark DataFrames, transformations, actions, joins, partitioning, execution behavior, optimization, and PySpark. Knowing how to write Spark code is useful; knowing why the Spark job is painfully slow is where the interesting expertise begins.
10. What Is the Difference Between Big Data and Data Science?
Big Data focuses heavily on infrastructure, storage, processing, pipelines, and scalable data systems. Data science focuses more on extracting insights and building statistical or machine-learning models from data. The fields overlap significantly. A simplified relationship is Big Data Engineering → Reliable Data → Analytics/Data Science → Insights and Models. Data scientists depend on trustworthy data infrastructure, while data engineers generally appreciate data scientists who do not request a 14-terabyte CSV by email.
11. What Is the Difference Between a Big Data Engineer and a Data Scientist?
A Big Data or data engineer builds the systems that collect, transform, store, and deliver data. A data scientist uses data to perform statistical analysis, experimentation, forecasting, and machine learning. Engineers focus on pipelines, architecture, reliability, scalability, and performance, while data scientists focus more heavily on analysis and modeling. In many organizations, these responsibilities overlap, particularly on smaller data teams.
12. Should Big Data Professionals Learn Cloud Computing?
Yes. Modern data platforms are heavily connected with cloud infrastructure. Big Data professionals should understand object storage, compute, databases, data warehouses, networking, identity and access management, monitoring, security, and cost optimization. Major cloud ecosystems include Amazon Web Services, Microsoft Azure, and Google Cloud. Start deeply with one platform, then learn transferable architectural concepts rather than attempting to memorize every service ever named by a cloud marketing department.
13. What Is a Data Lake, Data Warehouse, and Lakehouse?
A data lake stores large amounts of structured, semi-structured, and unstructured data, often in flexible object-storage formats. A data warehouse organizes curated data for analytics and business intelligence. A lakehouse attempts to combine aspects of both approaches, providing flexible storage with stronger management and analytical capabilities. Big Data experts should understand these architectures because storage design influences performance, governance, accessibility, reliability, and cost.
14. Should You Learn Real-Time Data Streaming?
Yes, especially for systems that process events continuously. Streaming architectures are useful for fraud detection, IoT, monitoring, recommendation systems, financial transactions, clickstreams, and operational analytics. Apache Kafka is an important technology to understand for event-driven and streaming data architectures. Learners should study topics, partitions, producers, consumers, delivery semantics, event schemas, and fault tolerance rather than treating Kafka as merely another item for the skills section.
15. What Big Data Projects Should Beginners Build?
Begin with projects that demonstrate complete data workflows. For example, ingest data from an API, store raw records, transform them with Python or Spark, load curated data into an analytical system, and create queries or a dashboard. More advanced projects can incorporate streaming, orchestration, data-quality checks, cloud infrastructure, and monitoring. A strong project explains Problem → Architecture → Data Pipeline → Transformation → Storage → Quality → Output → Results.
16. How Important Is Data Engineering for Big Data?
Data engineering is central to modern Big Data work. It includes ingestion, transformation, storage, orchestration, quality management, reliability, and data delivery. Organizations increasingly need data platforms that support analytics, machine learning, and generative AI simultaneously. As a result, learners should understand both batch and streaming pipelines, schema design, distributed processing, cloud storage, warehouses, observability, and data governance.
17. Do Big Data Experts Need to Learn AI and Machine Learning?
Not every Big Data professional needs to become a machine-learning engineer, but basic AI and ML knowledge is increasingly useful. Big Data infrastructure frequently supplies training, evaluation, retrieval, and analytical data to AI systems. Understanding feature pipelines, embeddings, vector data, model training requirements, and AI data governance can therefore broaden career opportunities. AI may attract the headlines, but somebody still has to make sure its data isn't a magnificent pile of inconsistent nonsense.
18. Do You Need a Degree to Become a Big Data Expert?
A degree in computer science, information technology, engineering, mathematics, or a related discipline can provide a strong foundation, but it is not the only path. Professionals can develop Big Data expertise through structured courses, certifications, projects, open-source work, and professional experience. Employers often care strongly about practical ability, particularly whether candidates can design pipelines, write SQL, work with distributed systems, troubleshoot failures, and explain architectural decisions.
19. How Long Does It Take to Become a Big Data Expert?
A beginner can develop foundational data skills over several months of consistent study, but genuine expertise typically requires much longer practical experience. The timeline depends on programming background, database knowledge, cloud experience, and the depth of specialization. Measure progress through Query Data → Build Pipelines → Process at Scale → Design Architecture → Optimize Performance → Secure Systems → Operate Reliably rather than counting completed courses.
20. What Is the Complete Roadmap to Become a Big Data Expert in 2026?
Start with programming and computing fundamentals:
Python → SQL → Linux → Git → APIs → Data Structures
Then learn databases and data modeling:
Relational Databases → NoSQL → Schema Design → Normalization → Dimensional Modeling → Query Optimization
Move into data engineering:
ETL/ELT → Data Ingestion → Transformation → Data Quality → Workflow Orchestration → Data Pipelines
Then study distributed processing:
Distributed Systems → Hadoop Concepts → Apache Spark → PySpark → Partitioning → Performance Optimization
Learn modern data architecture:
Data Warehouse → Data Lake → Lakehouse → Open Table Formats → Metadata and Catalogs
Add streaming:
Events → Apache Kafka → Stream Processing → Real-Time Pipelines
Then develop cloud skills:
Cloud Storage → Compute → Managed Databases → Warehouses → IAM → Networking → Monitoring → Cost Management
Governance and reliability come next:
Data Quality → Lineage → Observability → Security → Privacy → Governance → Disaster Recovery
Then understand the AI connection:
Data Pipelines → Machine Learning Data → Embeddings → Vector Data → Generative AI Data → AI Governance
Finally, choose a specialization:
Data Engineer
Big Data Engineer
Data Architect
Cloud Data Engineer
Streaming Data Engineer
Analytics Engineer
Data Platform Engineer
Data Engineering Lead
AI Data Engineer
The career-building process should run alongside the technical roadmap:
Learn → Practice → Build Projects → Document Architecture → Earn Relevant Certifications → Contribute → Gain Experience → Specialize
A strong portfolio might contain a batch-processing pipeline, a Spark project, a real-time streaming architecture, a cloud data platform, and a project integrating data engineering with machine learning or generative AI.
The overall formula is:
Python + SQL + Databases + Data Engineering + Distributed Systems + Spark + Streaming + Cloud + Governance + Projects
The biggest mistake is attempting to become an expert by memorizing dozens of technologies independently.
Learn the architecture first.
Understand how Data Sources → Ingestion → Processing → Storage → Serving → Analytics/AI fit together.
Tools will change. Platforms will be renamed. Vendors will discover fresh ways to describe databases as revolutionary.
The underlying data-engineering principles will remain considerably more useful.
Related Articles
View All
Big Data
How to Become a Big Data Expert in 2020?
We live in a society where data is now valued above gold. The reason for this is simple; our behavioural patterns as customers or consumers can be studied depending on the choices we make. And cumulatively, it collates as the data that determines business operations, customer behaviours, or…

Big Data
Essential Skills One Must Have to Become a Big Data Expert
Big data is becoming an inevitable word in today’s technology-driven era. Big data and data science technologies are driving organizations to make their decisions. It is no longer a buzz word as big data has now hit the mainstream. There has been tremendous growth in the tools and…
Big Data
Top Interview Questions for a Big Data Expert Interview
Big Data has become a part of everybody’s lives these days. Whether you realise it or not but simple activities like listening to music, watching videos, gaming, shopping, or even while ordering food, we leave our digital footprints everywhere. That’s what customizes the feed for you, and you enjoy…
Trending Articles
The Role of Blockchain in Ethical AI Development
How blockchain technology is being used to promote transparency and accountability in artificial intelligence systems.
AWS Career Roadmap
A step-by-step guide to building a successful career in Amazon Web Services cloud computing.
Top 5 DeFi Platforms
Explore the leading decentralized finance platforms and what makes each one unique in the evolving DeFi landscape.