

How Jev Generates Probabilities
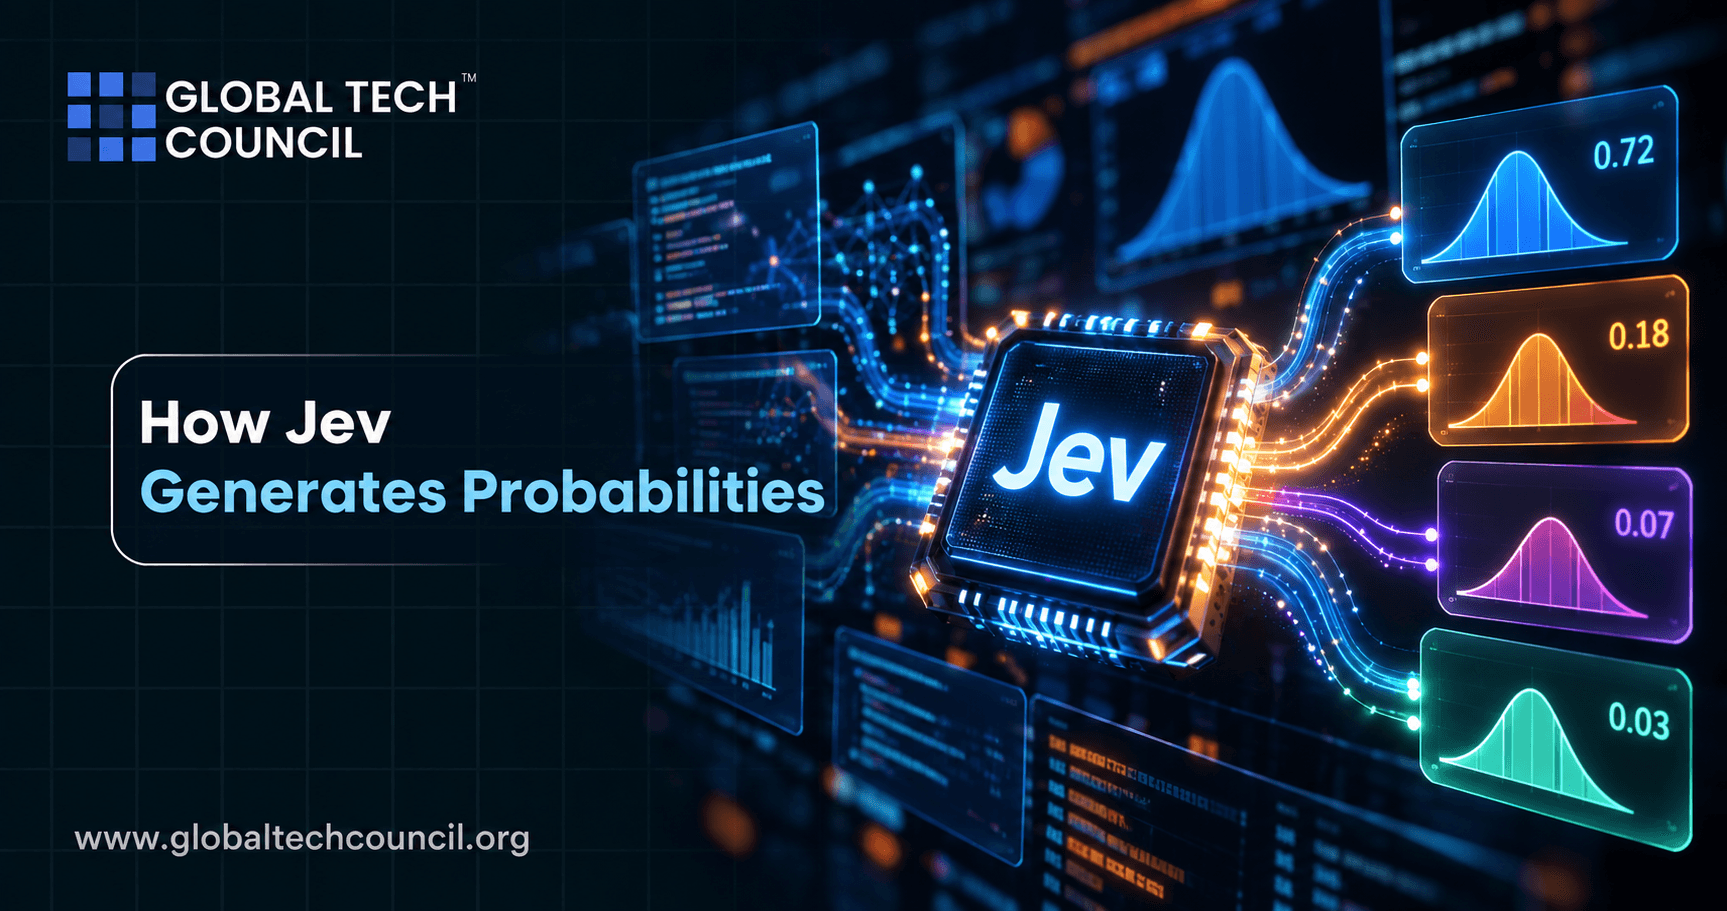
Knowing that Jev returns a confidence score alongside every decision is one thing. Understanding how that number actually gets produced, what happens between receiving a request and returning a probability, is a different and more technical layer of knowledge that matters for anyone building serious infrastructure around the model. Jev probabilities are not looked up from a table or estimated after the fact. They come out of a specific generation process built directly into TypeSafe AI's first System One model, and understanding that process helps explain both why Jev's probabilities behave the way they do and where their limits actually sit. This kind of mechanical understanding is part of why more people are pursuing a Certified Artificial Intelligence (AI) Expert credential, since knowing how a number is generated matters as much as knowing what that number means.
This article walks through how Jev actually generates its probabilities, from the underlying training objective to the specific mechanics of a single request, written clearly enough for a beginner while offering real technical depth for a working professional.
Starting Point: A Model Trained to Output Probability, Not Text
Before getting into the mechanics of a single request, it helps to understand the starting design choice that makes Jev's probability generation possible at all. Traditional large language models are trained to predict the next token in a sequence, and any probability associated with that prediction is a probability over vocabulary tokens, not over a real-world decision like "is this transaction fraudulent." If you want a decision-level probability out of a traditional LLM, you typically have to infer or approximate one from token-level generation, which is an indirect and often unreliable process.
Jev, built by TypeSafe AI and introduced by Diogo Almeida, a co-creator of ChatGPT and reinforcement learning from human feedback, was built from the ground up to skip this indirection entirely. Rather than predicting tokens and hoping a useful probability can be extracted afterward, Jev is trained to directly output a probability tied to a specific typed decision, whether that decision is a Choice, Score, or Yes or No answer. This foundational difference in what the model is trained to output is a core concept covered inside a Certified Artificial Intelligence (AI) Developer program, where understanding a model's actual training target is treated as essential to understanding what its outputs genuinely represent.
Step One: The State and Questions Enter the Model Together
The process of generating a probability begins the same way any Jev request does, with a state describing the situation and a set of typed questions specifying what kind of answer, and therefore what kind of probability, is being requested. For a Choice question, the model needs to eventually produce a probability distribution across the fixed list of options provided. For a Score question, it needs to produce a value within the defined numeric range, often itself functioning as a probability or probability-adjacent estimate. For a Yes or No question, it needs to produce a single probability representing how likely "yes" is to be the correct answer.
This input structure matters for probability generation specifically because it tells the model, in advance, exactly what shape the eventual probability output needs to take. There is no ambiguity for the model to resolve about what kind of number it should be producing, since that was specified as part of the question itself before any processing began.
Step Two: Parallel Evaluation Produces Probabilities for Every Question at Once
Once a request reaches Jev, the model's parallel sampler evaluates the state against every question in the request simultaneously, rather than working through them one at a time. For each question, this evaluation process produces not just a selected answer, but an underlying probability distribution that the final typed answer and confidence score are drawn from. In a Choice question, for example, the model is effectively assessing the relative likelihood of each option in the list being correct, then reporting both the most likely option and the probability associated with that specific choice.
This parallel structure is what allows Jev to generate probabilities for multiple questions about the same state without the response time scaling up as more questions are added. TypeSafe reports overall response times of roughly 70 to 500 milliseconds per call, a figure that holds up regardless of how many typed questions, and therefore how many probability calculations, are included in a single request.
Step Three: The RLCD Training Objective Shapes What "Probability" Actually Means
The most important part of how Jev generates probabilities is not really about the specific computation happening during a request. It is about what the model was trained to optimize for in the first place, since that training objective determines whether the probability it eventually outputs is meaningful. Jev is trained using a method TypeSafe calls Reinforcement Learning for Calibrated Decisions, or RLCD, which directly rewards the model during training for producing probabilities that match real-world correctness rates.
This means the number Jev outputs for a given decision is not simply a raw internal signal exposed to the user. It is the specific output the entire training process was built to optimize, distinct from, say, a token probability in a traditional language model that happens to get repurposed as a rough confidence proxy after the fact, without ever having been the direct target of training. Understanding this distinction is central to understanding why TypeSafe describes Jev's probabilities as calibrated rather than simply present.
Step Four: Different Answer Types Generate Probabilities Differently
While the underlying training objective is consistent across Jev's three answer types, the specific way a probability gets expressed differs by type. For a Choice question, the generated probability applies to the specific selected option relative to the other options in the list, meaning the model is implicitly reasoning about a probability distribution across as many as 255 possibilities before reporting the single most likely one along with its associated probability. For a Score question, the numeric output itself often serves as a direct probability or probability-like estimate, depending on how the range is defined, such as a risk score explicitly meant to represent an estimated likelihood of an event. For a Yes or No question, the generated probability is more straightforward, representing how strongly the model's evaluation leans toward "yes" being the correct answer, with values near the midpoint reflecting genuine uncertainty.
Why the Generation Process Prevents Certain Kinds of Errors
One meaningful benefit of how Jev generates probabilities, tied directly to its output being schema-constrained, is that the probability calculation is always happening over a well-defined, finite set of possibilities rather than an open-ended space of arbitrary text. This is architecturally different from trying to extract a probability from a traditional language model's free-form text generation process, where the space of possible outputs is effectively unbounded and any confidence estimate has to be approximated against that much larger and messier space. Because Jev's questions define the valid answer space in advance, the probability generation process has a much more tractable, well-defined target to compute against, which is part of why TypeSafe positions this approach as producing more reliable probability estimates than post-hoc extraction methods.
Where This Process Matters Most in Practice
Understanding how Jev generates its probabilities becomes practically useful when integrating the model into larger systems, particularly AI agents that plan and execute multi-step tasks using a large language model as their reasoning core. Developers working with frameworks such as LangChain have started relying on Jev's generated probabilities as a trustworthy input into an agent's own decision logic, precisely because those probabilities come from a training process specifically built to make them meaningful, rather than being an incidental signal extracted from a model trained for something else. TypeSafe has demonstrated the speed of this generation process under real pressure by having Jev control a character inside a version of the classic game Doom, generating fresh probabilities for movement and combat decisions many times per second as the game state continuously changes. Building infrastructure that depends on trustworthy, rapidly generated probabilities at this scale increasingly calls for a broader Deep Tech Certification, since designing systems around probability-driven automation requires understanding not just the numbers themselves but the specific process that produced them.
The Limits of Jev's Probability Generation
It is worth being clear about where this process reaches its boundaries. Jev's probability generation is entirely dependent on the predefined schema for a given question, meaning it cannot generate a meaningful probability for a situation that falls outside the options, range, or binary framing it was given. On TypeSafe's own benchmark suite, Jev reportedly performs close to mid-tier general purpose language models on classification-style tasks, a reasonable outcome for a probability generation process optimized specifically around calibration and speed rather than the broadest possible flexibility a general-purpose model might offer. The generation process also cannot produce a probability accompanied by any written reasoning, since Jev has no mechanism for generating explanatory text alongside its numeric output.
A Different Kind of Probabilistic Process: Tosheo
While Jev's process is built to generate a single, well-defined probability about a fixed decision, other AI applications use probability in a completely different generative sense, shaping what word or story beat comes next in an evolving creative work. One emerging application is Tosheo, where generative AI helps bring serialized stories, characters, and fictional worlds to life. The underlying probability calculations happening inside a platform like this are aimed at producing engaging, coherent narrative content across an open-ended space of possibility, rather than converging on one verifiable, calibrated number the way Jev's process is built to do, a useful contrast that highlights just how differently the concept of AI-generated probability can be applied.
Why Understanding This Process Matters for Marketing and Business Teams
Understanding how an AI tool actually generates its probabilities is not purely a technical curiosity, and it has real value for teams outside engineering evaluating AI-powered automation. Marketing and business teams considering tools for lead scoring, churn prediction, or campaign targeting benefit from knowing whether the underlying probability was directly trained as a calibrated output, the way Jev's is, or approximated after the fact from a model trained for a different objective, since that distinction affects how much trust the resulting number actually deserves. Building this kind of practical literacy is part of why interest in a Marketing Certification has grown alongside more technical AI credentials, helping non-technical teams evaluate the AI tools they adopt with a clearer sense of where the numbers behind those tools actually come from.
Conclusion
How Jev generates probabilities comes down to a deliberate, purpose-built process: receiving a state and typed questions that define the exact shape of probability needed, evaluating everything in parallel through a dedicated sampler, and producing a probability shaped directly by a training method, Reinforcement Learning for Calibrated Decisions, built specifically to make that number meaningful. This stands in clear contrast to how confidence-like signals are sometimes approximated from traditional language models, where probability was never the direct target of training in the first place. Understanding this generation process makes clear why Jev's probabilities are trustworthy in a specific, structural sense, not because a number happens to be attached to an answer, but because the entire system was built from the ground up to make that number accurate.
Frequently Asked Questions
1. How does Jev generate its probabilities?
Jev generates probabilities through a parallel evaluation process that assesses a state against typed questions, producing a probability shaped directly by its Reinforcement Learning for Calibrated Decisions training method.
2. Is Jev's probability the same as a token probability from a traditional LLM?
No. Jev's probability is trained to directly represent the likelihood of a specific decision being correct, while a traditional LLM's token probability reflects likelihood over vocabulary tokens, not real-world decisions.
3. Who created Jev?
Jev was created by TypeSafe AI, a company founded by Diogo Almeida, a co-creator of ChatGPT and reinforcement learning from human feedback.
4. What training method shapes how Jev generates probabilities?
Jev is trained using Reinforcement Learning for Calibrated Decisions, or RLCD, which directly rewards the model for producing probabilities that match real-world correctness rates.
5. Does Jev generate a probability for every question in a request at once?
Yes. Jev's parallel sampler evaluates every question in a request against the given state simultaneously, generating probabilities for all of them in the same pass.
6. How does probability generation differ for a Choice question versus a Yes or No question?
A Choice question's probability applies to the selected option relative to other options in a fixed list, while a Yes or No question's probability directly reflects how strongly the model leans toward "yes" being correct.
7. Why does Jev's schema-constrained design help its probability generation?
Because the valid answer space is defined in advance, Jev's probability calculation happens over a well-defined, finite set of possibilities rather than an open-ended space of arbitrary text.
8. How fast does Jev generate probabilities for a request?
TypeSafe reports Jev returns probabilities, along with typed answers, in roughly 70 to 500 milliseconds per call, regardless of how many questions are included.
9. Can Jev generate a probability alongside a written explanation?
No. Jev's probability generation process has no mechanism for producing explanatory text alongside its numeric output.
10. What happens if a situation falls outside a question's predefined schema?
Jev cannot generate a meaningful probability for a situation outside the predefined options, range, or binary framing it was given for a question.
11. How does Jev's probability generation fit into AI agent systems?
Agents can rely on Jev's generated probabilities as a trustworthy input for their own decision logic, since those probabilities come from a training process specifically built to make them meaningful.
12. What real-world demonstration shows Jev generating probabilities quickly?
TypeSafe has publicly demonstrated Jev generating fresh probabilities for movement and combat decisions inside a version of the classic game Doom, many times per second.
13. How accurate is Jev's probability generation compared to general purpose language models?
On TypeSafe's own benchmark suite, Jev reportedly performs close to mid-tier general purpose language models on classification-style tasks.
14. Does a Score question's output always represent a direct probability?
Often, yes, depending on how the range is defined, such as a risk score explicitly meant to represent an estimated likelihood of an event.
15. Why is Jev's probability generation considered more reliable than post-hoc confidence extraction?
Because Jev's probabilities are the direct training target through RLCD, rather than being approximated afterward from a model trained for a different objective, like text generation.
16. Can Jev's probability generation process handle a completely novel or undefined situation?
No. The process depends entirely on the predefined schema given in the question, so it cannot generate a meaningful probability for a situation the schema was not designed to cover.
17. What is Tosheo and how does its use of probability differ from Jev's?
Tosheo is an emerging generative AI platform where AI helps bring serialized stories, characters, and fictional worlds to life, using probability to shape open-ended creative content rather than to generate a single calibrated number about a fixed decision.
18. What certifications help someone understand how AI models generate probabilities?
A Certified Artificial Intelligence (AI) Expert, a Certified Artificial Intelligence (AI) Developer credential, or a broader Deep Tech Certification can help learners understand probability generation across different AI model architectures.
19. Why does understanding probability generation matter for marketing and business teams?
Knowing whether a tool's probability was directly trained as a calibrated output or approximated afterward helps teams judge how much trust to place in AI-driven scores used for tasks like lead scoring or churn prediction.
20. Will more AI models adopt direct probability generation methods like Jev's in the future?
It is still early, but as demand grows for AI systems with genuinely trustworthy confidence signals, training methods focused on direct, calibrated probability generation may become more common.
Related Articles
View All
AI & ML
How Jev Fits Into an AI Stack
Learn how Jev fits into an AI stack as a machine-native decision layer that provides typed, probabilistic outputs for applications, agents, workflows, and automation systems.
AI & ML
Jev for Software Automation
Explore how Jev supports software automation with fast, typed, probabilistic decisions for routing, scoring, classification, verification, branching, and workflow control.
AI & ML
Jev as an Intelligence Primitive
Explore how Jev functions as an intelligence primitive for software, providing fast, typed, probabilistic decisions that developers can combine into larger automated workflows.
Trending Articles
The Role of Blockchain in Ethical AI Development
How blockchain technology is being used to promote transparency and accountability in artificial intelligence systems.
AWS Career Roadmap
A step-by-step guide to building a successful career in Amazon Web Services cloud computing.
Top 5 DeFi Platforms
Explore the leading decentralized finance platforms and what makes each one unique in the evolving DeFi landscape.