

How the Jev Architecture Works
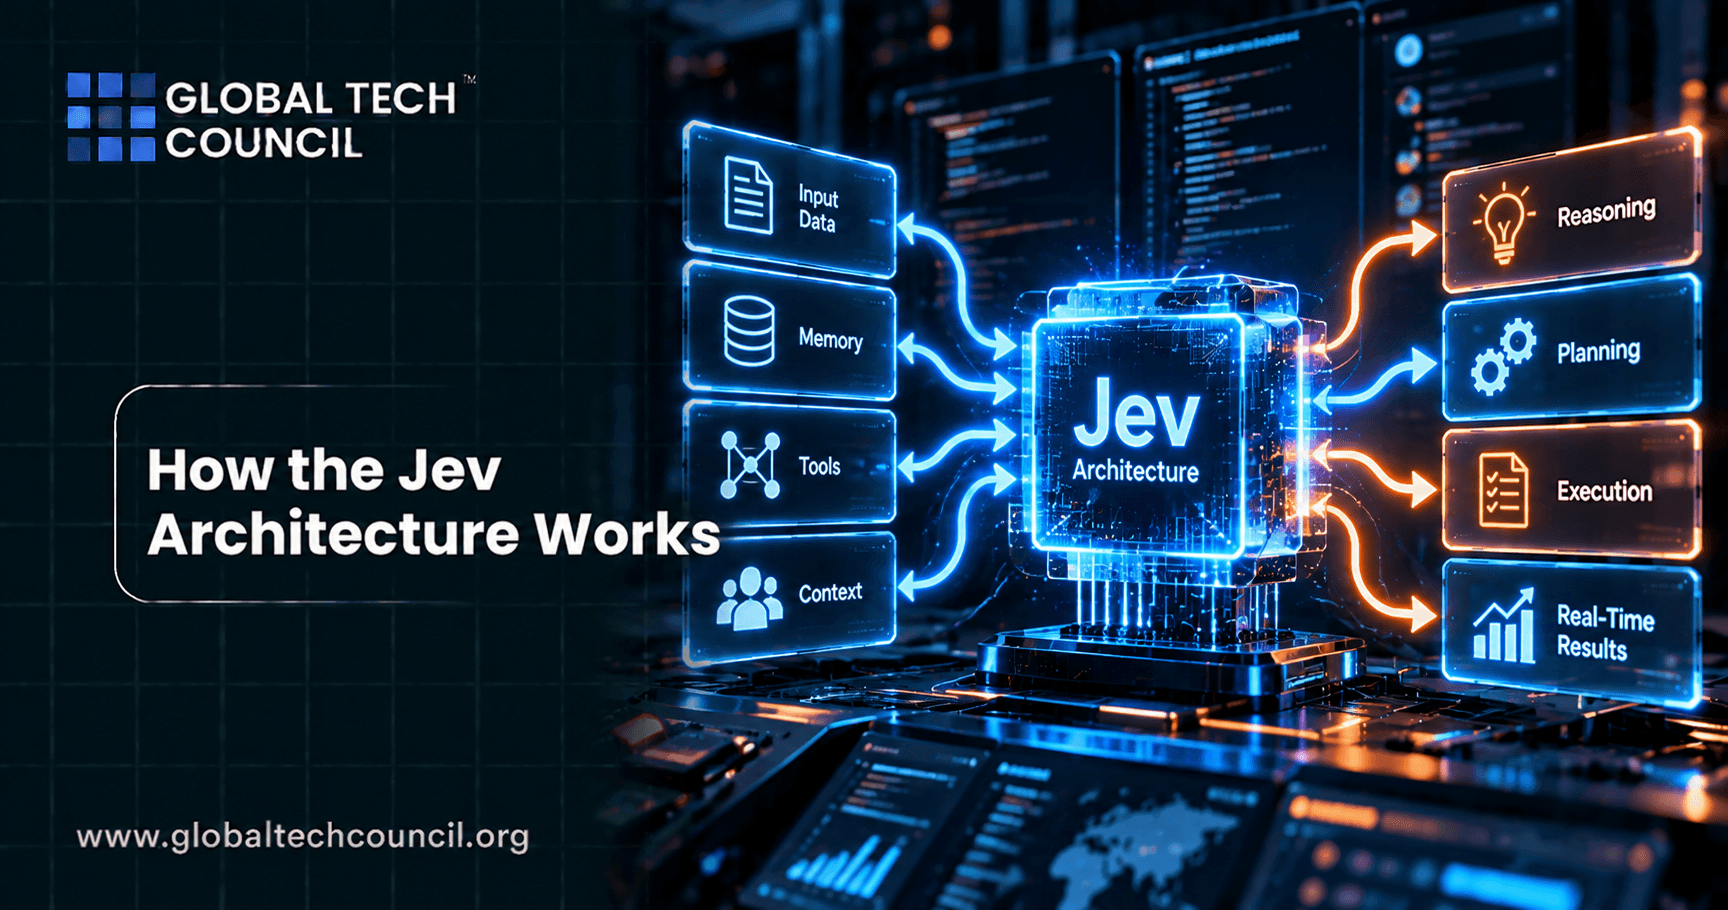
Understanding what Jev does is one thing. Understanding how it actually gets there, step by step, is a different and more useful kind of knowledge, especially for anyone deciding whether to build on top of it. The Jev architecture is not just "a faster AI model." It is a specific sequence of design choices, from how a request enters the system to how a typed answer comes back out, that together produce the speed and reliability TypeSafe AI has been demonstrating publicly since its September 2026 launch. Walking through that sequence in order is a useful way to build real technical fluency, which is part of why more people are pursuing a Certified Artificial Intelligence (AI) Expert credential to understand not just what AI models do, but how their internal processes actually function.
This article walks through how the Jev architecture works from start to finish, following a single request through the system step by step, explained clearly enough for a beginner while offering real technical substance for a working professional.
Step One: A Request Arrives as State Plus Questions
Every interaction with Jev begins the same way: a request containing two distinct parts. The first part is the state, a block of unstructured context describing whatever situation needs to be evaluated, such as the contents of a support ticket, the current layout of a game environment, or details of a financial transaction. The second part is a list of typed questions, each one specifying in advance exactly what kind of answer is valid for that question.
This is a meaningful departure from how a traditional large language model receives a prompt. An LLM typically gets a single block of text and has to infer, from context and instructions, what kind of response the user actually wants. Jev's architecture removes that inference step entirely by separating the situation from the exact shape of the decision being requested, which is the first of several design choices that trace back to Jev's core goal of eliminating ambiguity from automated decision-making. Understanding why this separation matters is part of what a Certified Artificial Intelligence (AI) Developer program covers when teaching how input design shapes a model's reliability in production systems.
Step Two: The Model Evaluates Every Question at Once
Once a request reaches Jev, the next step is where the architecture diverges most sharply from a traditional language model. Rather than answering one question, generating a full response, and then moving on to the next, Jev evaluates every question in the request against the given state simultaneously, in a single parallel pass. This is made possible by a parallel sampler TypeSafe built specifically for this purpose, rather than adapting an existing sequential text-generation pipeline.
The practical effect of this step is significant. Because there is no sequential dependency between answering one question and the next, adding more questions to a single request barely changes how long the overall response takes. TypeSafe reports that Jev responds in roughly 70 to 500 milliseconds per call, a figure that holds up whether a request contains one typed question or several, which stands in sharp contrast to a traditional LLM, where a longer or more complex response takes proportionally longer to generate because each additional token depends on the ones that came before it.
Step Three: Each Answer Is Constrained to a Predefined Schema
As Jev processes each question, its architecture restricts the possible output to one of three predefined formats. A Choice answer selects one option from a fixed list of up to 255 possibilities, appropriate for categorizing a situation. A Score answer returns a numeric rating within a defined range, appropriate for tasks like risk assessment. A Yes or No answer returns a simple binary judgment, appropriate for approve-or-flag decisions.
This constraint is not a filter applied after the fact. It is built into the architecture itself, meaning there is structurally no path for Jev to produce an answer outside the schema defined for a given question. This is the specific architectural reason TypeSafe states that Jev cannot hallucinate an invalid response, a stronger and more structural guarantee than simply instructing a language model to stick to a certain format and hoping it complies.
Step Four: A Calibrated Confidence Score Gets Attached
Alongside each typed answer, Jev's architecture attaches a calibrated confidence score, reflecting how certain the model actually is about that particular decision. This step is where Jev's training method becomes directly visible in its output. The model is trained using Reinforcement Learning for Calibrated Decisions, or RLCD, a method built by TypeSafe specifically to reward honest, well-calibrated confidence rather than fluent, convincing-sounding text, which is closer to the objective used to train many general purpose language models.
This means that when Jev reports a confidence score of, say, 85 percent for a given Choice answer, that number is meant to genuinely reflect an 85 percent likelihood of being correct, based on how the model was trained and evaluated, rather than being an arbitrary number attached for the sake of appearing thorough. This step is what allows downstream software to make smart decisions about how to treat each answer, automatically acting on high-confidence results while routing lower-confidence ones to a human reviewer.
Step Five: The Typed Response Returns to the Calling System
The final step in the architecture is returning the completed set of typed answers and confidence scores back to whatever system made the original request. Because every answer is already in a fixed, predictable format, there is no parsing step required on the receiving end, unlike a traditional LLM response, which often needs to be interpreted or extracted from free-form text before software can act on it.
This clean handoff is exactly what makes Jev's architecture well suited to sit inside larger automated systems, particularly AI agents that plan and execute multi-step tasks using a large language model as their reasoning core. Developers working with frameworks such as LangChain have taken advantage of this by inserting Jev as a decision layer between tool calls, letting the agent receive a typed, ready-to-use answer rather than a block of text it needs to interpret before deciding what to do next.
Watching the Architecture in Action
TypeSafe has demonstrated how this full sequence, state and questions in, parallel evaluation, typed and confidence-scored output back out, performs under real pressure by having Jev control a character inside a version of the classic game Doom. In that environment, the model needs to receive a constantly updating state describing the game world, evaluate several typed questions about movement and combat, and return decisions many times per second, a workload that directly exercises every step of the architecture described above at a pace a sequential, token-by-token model would struggle to sustain. Building systems that take advantage of this kind of architecture at scale increasingly calls for a broader Deep Tech Certification, since designing infrastructure around a parallel, typed-decision model requires a different set of engineering considerations than working with a traditional sequential language model.
Why Each Step Exists: Tracing Back to the Core Design Goal
It is worth stepping back and noting how directly each part of this process traces back to Jev's founding design goal: fast, reliable, structured decisions rather than open-ended text. The state-and-questions input structure removes ambiguity before processing even begins. The parallel evaluation step eliminates the latency penalty of sequential generation. The schema-constrained output format guarantees a usable, predictable answer every time. The calibrated confidence score, trained through RLCD, gives that answer a meaningful and honest reliability signal. And the clean, typed handoff back to the calling system removes the need for any parsing layer. None of these steps exist independently. Each one supports and depends on the others to deliver the overall speed and reliability TypeSafe has publicly reported.
Where the Architecture Reaches Its Limits
Every step in this process also reveals where the architecture intentionally stops. Because the entire pipeline is built around evaluating predefined typed questions against a given state, Jev's architecture has no mechanism for open-ended reasoning, explanation, or free-form content generation at any step. It cannot handle a question that falls outside its predefined schema, and it cannot produce an answer accompanied by a written justification. On TypeSafe's own benchmark suite, Jev reportedly performs close to mid-tier general purpose language models on classification-style tasks, a solid outcome for an architecture optimized primarily for speed and calibration rather than the broadest possible range of task types.
A Very Different Kind of Process: Tosheo
While Jev's architecture is built around a tightly defined, repeatable sequence that narrows down to one confident, typed answer, other AI applications follow an entirely different kind of process built around expanding possibility rather than constraining it. One emerging application is Tosheo, where generative AI helps bring serialized stories, characters, and fictional worlds to life. Watching how a platform like this processes a request, generating open-ended narrative content rather than a fixed typed answer, makes the contrast with Jev's step-by-step decision pipeline especially clear, and is a useful reminder of just how differently AI systems can be architected depending on their intended purpose.
Why Understanding This Process Matters for Business Teams
Knowing how the Jev architecture actually works, step by step, is not purely a technical exercise. It has real implications for how businesses evaluate and adopt AI tools, since understanding a tool's underlying process reveals what it can reliably deliver and where its boundaries sit. Marketing and operations teams considering AI-powered automation benefit from understanding whether a tool's process is built around structured, repeatable decision-making or open-ended content generation, since that distinction shapes what results to expect. Building this kind of technical literacy is part of why interest in a Marketing Certification has grown alongside more technical AI credentials, helping non-technical teams evaluate AI tools with a clearer sense of how they actually function underneath the surface.
Conclusion
The Jev architecture works through a deliberate, five-step process: receiving a state and typed questions, evaluating every question in parallel rather than sequentially, constraining each answer to a predefined schema, attaching a calibrated confidence score trained through Reinforcement Learning for Calibrated Decisions, and returning a clean, ready-to-use typed response. Each step exists to serve the same underlying goal, delivering fast, reliable, structured decisions without the latency, cost, or ambiguity that comes with routing the same task through a traditional text-generating language model. Understanding this process makes clear that Jev's speed is not an accident of clever engineering layered on top of an existing model, but the direct result of an architecture built from the ground up around a fundamentally different objective.
Frequently Asked Questions
1. What is the first step in how the Jev architecture works?
The process begins when Jev receives a request containing a state, which is unstructured context describing a situation, and a set of typed questions specifying the exact kind of answer required.
2. How does Jev evaluate multiple questions in a single request?
Jev evaluates every question in a request against the given state simultaneously, in a single parallel pass, rather than answering them one after another.
3. Who created Jev?
Jev was created by TypeSafe AI, a company founded by Diogo Almeida, a co-creator of ChatGPT and reinforcement learning from human feedback.
4. What answer types can Jev return in its architecture?
Jev can return Choice answers from a fixed list of up to 255 options, numeric Score answers, and Yes or No answers, each constrained to a predefined schema.
5. Why can't Jev return an answer outside its predefined schema?
Because the schema constraint is built directly into Jev's architecture, there is structurally no path for the model to generate a response outside the valid answer set for a given question.
6. What role does confidence scoring play in Jev's process?
Each answer comes with a calibrated confidence score, trained through Reinforcement Learning for Calibrated Decisions, reflecting how certain the model actually is about that particular decision.
7. What training method produces Jev's calibrated confidence scores?
Jev is trained using Reinforcement Learning for Calibrated Decisions, or RLCD, a method specifically designed to reward honest, well-calibrated confidence rather than convincing-sounding text.
8. How fast does the overall Jev process complete?
TypeSafe reports that the full process, from receiving a request to returning typed answers, takes roughly 70 to 500 milliseconds per call.
9. Why does adding more questions barely slow down Jev's process?
Because every question in a request is evaluated in the same parallel pass rather than sequentially, additional questions add minimal extra processing time.
10. What happens after Jev returns its typed answers?
The typed answers and confidence scores are returned directly to the calling system, which can act on them immediately without needing to parse free-form text.
11. How does Jev's process fit into AI agent workflows?
Jev's clean, typed input and output structure allows it to serve as a fast decision layer between tool calls in an agent's workflow, without requiring a parsing step.
12. What real-world demonstration highlights each step of Jev's process?
TypeSafe has publicly demonstrated Jev controlling a character inside a version of the classic game Doom, exercising the full request-to-response process many times per second.
13. Can Jev generate an explanation alongside its typed answers?
No. Jev's architecture has no step for generating free-form text or explanations, focusing entirely on typed, structured decision outputs.
14. Why is the state-and-questions input structure important to Jev's process?
Separating the situation from the exact shape of the requested answer removes ambiguity before processing even begins, making the model's output more predictable and reliable.
15. How accurate is Jev's process compared to traditional AI models?
On TypeSafe's own benchmark suite, Jev reportedly performs close to mid-tier general purpose language models on classification-style tasks, while completing its process significantly faster.
16. What is the main limitation revealed by walking through Jev's process?
Every step in Jev's process is built around evaluating predefined typed questions, so it has no mechanism for handling open-ended reasoning or questions outside its schema.
17. What is Tosheo and how does its process differ from Jev's?
Tosheo is an emerging generative AI platform where AI helps bring serialized stories, characters, and fictional worlds to life, following an open-ended generative process that contrasts sharply with Jev's structured, step-by-step decision pipeline.
18. What certifications help someone understand processes like Jev's architecture?
A Certified Artificial Intelligence (AI) Expert, a Certified Artificial Intelligence (AI) Developer credential, or a broader Deep Tech Certification can help learners understand both traditional and newer step-by-step model architectures.
19. Why does understanding Jev's process matter for businesses adopting AI tools?
Understanding how a tool's underlying process works helps teams judge what results to expect and whether the tool fits a structured decision task or a language-based task.
20. Is the process behind Jev's architecture likely to influence future AI model designs?
It is still early, but the step-by-step parallel, typed-decision process behind Jev is drawing attention as a potential blueprint for future models built around fast, structured decision-making.
Related Articles
View All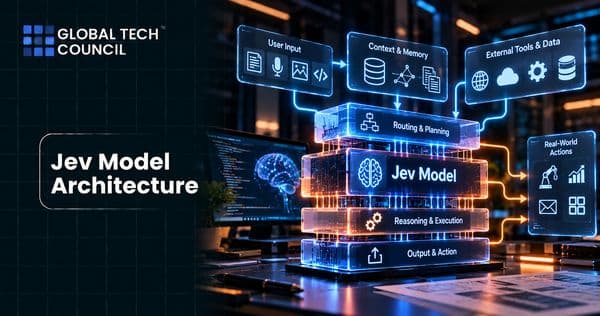
AI & ML
Jev Model Architecture
Explore the Jev model architecture, including TypeSafe AI’s System One design, parallel sampling, RLCD training, typed outputs, and calibrated probabilistic decisions.
AI & ML
Jev Architecture Explained
Explore Jev’s architecture, including TypeSafe AI’s System One design, parallel sampling, RLCD training, typed outputs, calibrated probabilities, and machine-native decision-making.
AI & ML
Jev Structured Outputs Explained
Learn how Jev structured outputs work, including predefined response types, calibrated probabilities, confidence scores, and how software can use decisions directly in automated workflows.
Trending Articles
The Role of Blockchain in Ethical AI Development
How blockchain technology is being used to promote transparency and accountability in artificial intelligence systems.
AWS Career Roadmap
A step-by-step guide to building a successful career in Amazon Web Services cloud computing.
Top 5 DeFi Platforms
Explore the leading decentralized finance platforms and what makes each one unique in the evolving DeFi landscape.