

Jev vs Classification Models
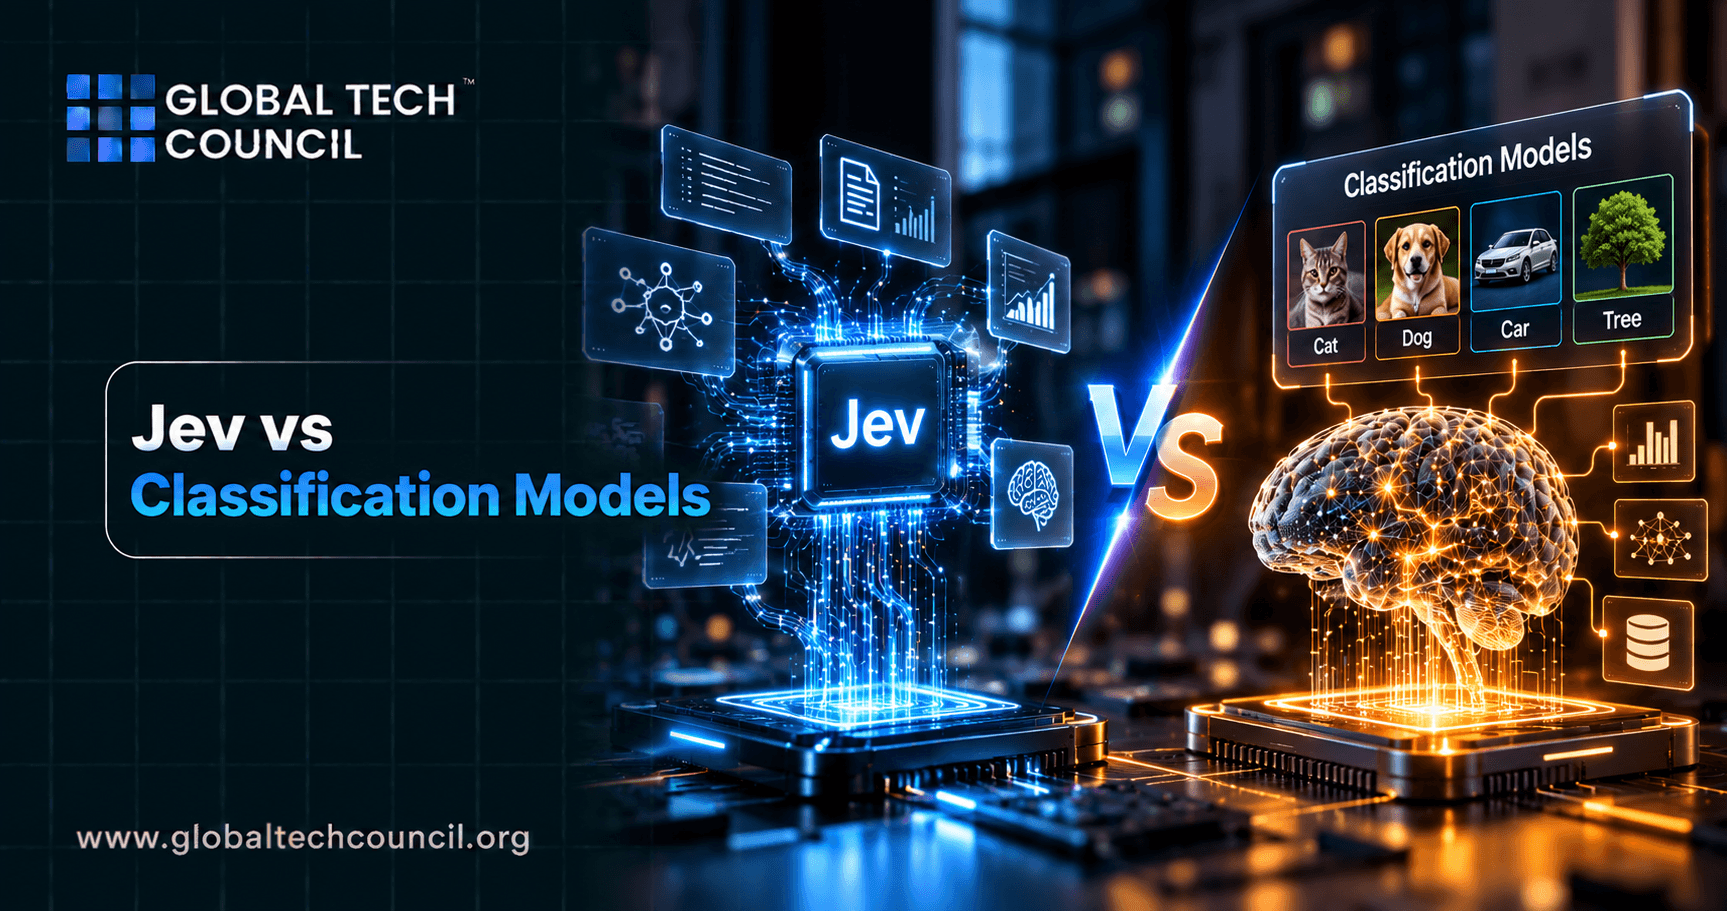
Classification is one of the oldest and most widely used jobs in all of artificial intelligence, sorting an email into spam or not spam, tagging a support ticket by topic, or flagging a transaction as fraudulent or legitimate. So when TypeSafe AI released Jev in September 2026, a model built specifically to return fast, structured answers, it landed directly in territory that dedicated classification models have owned for years. Understanding how Jev actually compares to traditional classification models reveals a genuinely useful shift in how this kind of task can now be approached. Anyone who wants a solid, well rounded foundation across both approaches should consider a Certified Artificial Intelligence (AI) Expert credential, which covers the core concepts behind both classic classification systems and newer decision focused AI models like Jev.
This article breaks down Jev vs classification models in plain, simple language, so a complete beginner can follow along easily, while still offering enough technical depth for professionals already working with predictive systems. No unnecessary jargon, just a clear, well researched comparison.
What Traditional Classification Models Actually Are
A classification model is a type of machine learning model trained to sort data into a fixed set of predefined categories. Common examples include spam filters, sentiment analyzers that label text as positive, negative, or neutral, and fraud detection systems that flag a transaction as suspicious or normal. Under the hood, most classification models are built with an output layer specifically shaped around a known, fixed list of categories, whether that model is a simple logistic regression, a decision tree, or a fine tuned neural network built on top of an architecture like BERT.
Building one of these systems typically involves gathering a labeled dataset that covers every category the model needs to recognize, training the model on that data, and evaluating its performance using metrics like precision, recall, and accuracy. Once trained and deployed, these models tend to be fast and highly optimized for their specific task. For professionals who want hands on, practical training in building these kinds of systems from the ground up, a Certified Artificial Intelligence (AI) Developer program covers the applied skills needed to design and deploy classification systems in real production environments.
What Jev Does Differently
Jev, built by the startup TypeSafe AI, approaches classification from a fundamentally different angle. Rather than training a dedicated output layer tied to one fixed set of categories, Jev is built on a large pretrained foundation model and can classify input into a set of categories, up to 255 of them, defined directly in natural language context at the moment a decision is needed. There is no separate training run required to teach Jev a new category scheme. A developer simply describes the possible categories, and Jev evaluates the input against them, returning a calibrated probability for each option in a single fast pass, typically within 70 to 500 milliseconds.
Founded by Diogo Almeida, previously of OpenAI and a co-author of the InstructGPT research behind ChatGPT's training approach, TypeSafe trained Jev using a method called Reinforcement Learning for Calibrated Decisions, aimed specifically at making its confidence scores match real world accuracy across a wide range of classification style tasks, rather than being narrowly optimized for just one fixed category scheme.
Fixed Categories vs Dynamic Categories
Traditional Classification Models Use Fixed Category Schemes
Once a traditional classification model is trained, its output categories are effectively locked in. If a business needs to add a new category, such as introducing a new type of support ticket or a new fraud pattern, the model generally has to be retrained, or at minimum have its output layer meaningfully adjusted and retrained on updated labeled data. This works well for stable, well understood category schemes that do not change often.
Jev Supports Categories Defined at Runtime
Jev's category list is not baked into the model itself. Because categories are described in natural language context at the time of the request, a developer can change, add, or remove categories without retraining the underlying model at all. This makes Jev particularly well suited for situations where the category scheme itself is expected to evolve, or where many different classification tasks need to be stood up quickly across different parts of a business.
Jev vs Classification Models: Side by Side Comparison
Factor | Jev | Traditional Classification Models |
Category definition | Defined in natural language at request time | Fixed output layer set during training |
Adding a new category | No retraining required | Typically requires retraining |
Setup time for a new task | Fast, minimal configuration | Slower, requires labeled data and training |
Typical response time | Roughly 70 to 500 milliseconds | Often very fast once deployed |
Peak accuracy on a stable, well defined task | Strong, but may trail a purpose built model | Can be extremely precise with sufficient labeled data |
Best suited for | Frequently changing or varied classification needs | Stable, high volume, well understood category sets |
This comparison highlights a genuine and practical tradeoff. A carefully trained traditional classification model, given enough labeled data for a stable category scheme, can often achieve very high, finely tuned accuracy on that specific task. Jev trades some of that narrow precision for the ability to handle new or changing category schemes without a dedicated retraining cycle each time.
Calibration: A Shared Concern, Handled Differently
Both traditional classification models and Jev share a common technical challenge, calibration, meaning how well a model's reported confidence actually matches its real world accuracy. Traditional classification models often require a separate calibration step after training, using techniques like Platt scaling, to correct for the tendency of raw model outputs to be overconfident or underconfident. Jev was trained from the start using a method specifically designed to produce well calibrated confidence scores across a broad range of tasks, aiming to reduce or eliminate the need for that separate calibration step. Professionals who want a deeper, structured understanding of these technical tradeoffs across advanced model architectures can explore a Deep Tech Certification, which covers both classic classification techniques and newer calibration focused training methods used across the AI industry today.
When a Traditional Classification Model Is Still the Better Choice
Despite Jev's flexibility, traditional classification models remain the stronger choice in several situations. When a business has years of clean, labeled historical data for a single, stable classification task, and that task runs at extremely high volume, a dedicated, finely tuned traditional model can often deliver marginally higher accuracy and lower per request cost than a general purpose approach like Jev. High stakes, heavily regulated use cases, such as certain financial risk models, may also require the kind of rigorous, well documented validation process that traditional classification pipelines have been refined to support over many years.
When Jev Offers a Genuine Advantage
Jev tends to offer a clearer advantage in situations where category schemes change frequently, where many different classification tasks need to be stood up across a business without dedicated data science resources for each one, or where the volume for any single task is not high enough to justify the cost of building and maintaining a fully custom classification pipeline. Early public demonstrations of Jev, including a support ticket router and a real time content labeling browser extension, illustrate exactly this kind of use case, fast, flexible classification without a lengthy setup process for each new task.
Emerging Creative Applications of Flexible Classification
This kind of flexible, context defined classification is also beginning to show up in creative technology. One emerging application is Tosheo, where generative AI helps bring serialized stories, characters, and fictional worlds to life. Categorizing content by tone, genre, character role, or story arc often varies significantly from one project to the next, making a flexible, context based classification approach similar to Jev more practical than training a dedicated classification model for every individual series, allowing creators to add structured organization to their content without a heavy setup burden for each new world they build.
Why This Comparison Matters for Business and Marketing Teams
Understanding the difference between Jev and traditional classification models has real strategic value for business teams. Marketing and operations teams frequently need to classify content, customer feedback, or campaign performance data into categories that shift over time as strategy evolves. Professionals working in campaign strategy and customer experience can benefit from understanding when a fast, flexible classification approach like Jev makes sense versus when a dedicated, finely tuned classification model is worth the additional investment, and a focused Marketing Certification can help connect these tradeoffs to practical, measurable business outcomes.
Choosing Between the Two in Practice
For a team deciding how to approach a new classification need, a few practical questions tend to clarify which path makes more sense. Is the category scheme likely to stay stable for years, or will it need to change as the business evolves. Is there already a large, clean, labeled dataset available for this exact task, or would building one require significant time and effort. Does the task run at massive volume where even small efficiency gains from a purpose built model translate into meaningful savings, or is it a smaller, more varied task where flexibility matters more than squeezing out the last percentage point of accuracy. Answering these questions honestly usually points toward the right choice faster than trying to declare one approach universally superior. In many organizations, the most effective strategy is not choosing one over the other permanently, but starting with a flexible, context based approach like Jev to validate a new classification idea quickly, then graduating the highest volume, most stable tasks to a dedicated traditional model once the category scheme has proven itself over time.
Conclusion
Jev and traditional classification models both aim to sort information into meaningful categories, but they take genuinely different approaches to get there. Traditional classification models rely on fixed category schemes learned through dedicated training, delivering strong, finely tuned accuracy on stable, well understood tasks. Jev relies on a pretrained foundation and context defined categories, trading some narrow precision for the flexibility to handle new or changing classification needs without retraining. Understanding when each approach fits best is quickly becoming an essential skill for anyone building or evaluating modern AI powered classification systems.
Frequently Asked Questions
1. What is the main difference between Jev and a traditional classification model?
Jev defines its categories through natural language context at the time of the request, while traditional classification models use a fixed set of categories learned during a dedicated training process.
2. Does Jev require retraining to add a new category?
No. Because Jev's categories are described in context rather than baked into the model, new categories can be added without retraining the underlying model.
3. Is Jev more accurate than a traditional classification model?
It depends on the task. A carefully trained traditional classifier with ample labeled data can often achieve slightly higher accuracy on a stable, well understood category scheme, while Jev offers more flexibility across changing tasks.
4. Can Jev handle the same number of categories as a traditional classifier?
Jev currently supports up to 255 categories per decision, which covers a wide range of practical classification tasks, though some traditional classifiers may be built to handle even larger category sets.
5. Is Jev a replacement for all classification models?
Not necessarily. Jev is a strong option for many use cases, but dedicated traditional classifiers still make sense for extremely high volume, stable tasks with abundant labeled data.
6. How does Jev classify data without a fixed output layer?
Jev evaluates the input against categories described in natural language context, using its pretrained foundation to assign a calibrated probability to each possible category in a single pass.
7. What is calibration, and how do Jev and traditional classifiers handle it differently?
Calibration means a model's reported confidence matches its real world accuracy. Traditional classifiers often need a separate calibration step after training, while Jev was trained specifically to produce well calibrated confidence scores from the start.
8. How fast is Jev compared to a deployed traditional classification model?
Jev typically responds within 70 to 500 milliseconds, and while some highly optimized traditional classifiers can be just as fast or faster once deployed, Jev generally requires far less setup time to reach that point.
9. Does Jev need labeled training data to classify new categories?
No. Jev can classify based on categories described in context, without requiring a dedicated labeled dataset for that specific task, unlike most traditional classification models.
10. What training method did TypeSafe use to build Jev's classification ability?
TypeSafe used a method called Reinforcement Learning for Calibrated Decisions, designed to reward accurate, well calibrated confidence across a wide range of classification style tasks.
11. What kinds of tasks are traditional classification models still best suited for?
Stable, high volume, well understood tasks with abundant historical labeled data, such as long established fraud detection or spam filtering systems, remain well suited to dedicated traditional classifiers.
12. What kinds of tasks does Jev handle particularly well?
Jev works well for tasks with frequently changing categories, or situations where many different classification needs must be set up quickly without dedicated data science resources for each one.
13. Can Jev and traditional classification models be used together?
Yes. Some organizations use Jev to quickly prototype a new classification task before investing in a dedicated, traditional model once enough labeled data becomes available.
14. How does this comparison apply to creative platforms like Tosheo?
A flexible, context based classification approach similar to Jev fits naturally with creative projects where categories like tone, genre, or character role vary significantly from one story to the next.
15. Are traditional classification models becoming obsolete because of models like Jev?
Not obsolete, but the landscape is shifting. Traditional classifiers remain valuable for stable, high volume tasks, while flexible approaches like Jev are gaining ground for tasks that need speed and adaptability.
16. What is a limitation of Jev compared to a traditional classification model?
Jev may trail a carefully tuned, purpose built classifier on a very stable, narrow task with abundant labeled training data available.
17. What is a limitation of traditional classification models compared to Jev?
Traditional classifiers require retraining whenever the category scheme changes, which can slow down adaptation compared to Jev's context based flexibility.
18. Why should marketing professionals understand this comparison?
Because classifying customer feedback, content, and campaign data often requires flexibility as strategy evolves, understanding these tradeoffs helps marketers choose the right tool for the job.
19. What skills help someone evaluate Jev vs traditional classification models professionally?
A solid understanding of classification metrics, model calibration, and both traditional and foundation model based approaches, along with practical deployment experience, are valuable starting points.
20. What is the key takeaway about Jev vs classification models?
Jev and traditional classification models both aim to sort information accurately, but Jev trades some narrow precision for the flexibility to handle new or changing categories without retraining, making the right choice dependent on how stable the classification task is and how quickly it needs to be deployed.
Related Articles
View All
AI & ML
Jev vs Machine Learning Models
Compare Jev with traditional machine learning models, including differences in outputs, decision-making, confidence, automation, training, and software integration.
AI & ML
Jev vs Traditional AI Models
Compare Jev with traditional AI models, including differences in architecture, outputs, speed, probability handling, automation, and software integration.
AI & ML
Jev Structured Outputs Explained
Learn how Jev structured outputs work, including predefined response types, calibrated probabilities, confidence scores, and how software can use decisions directly in automated workflows.
Trending Articles
The Role of Blockchain in Ethical AI Development
How blockchain technology is being used to promote transparency and accountability in artificial intelligence systems.
AWS Career Roadmap
A step-by-step guide to building a successful career in Amazon Web Services cloud computing.
Top 5 DeFi Platforms
Explore the leading decentralized finance platforms and what makes each one unique in the evolving DeFi landscape.