Meet Nanbeige 4.3: The New Open-Source AI Model
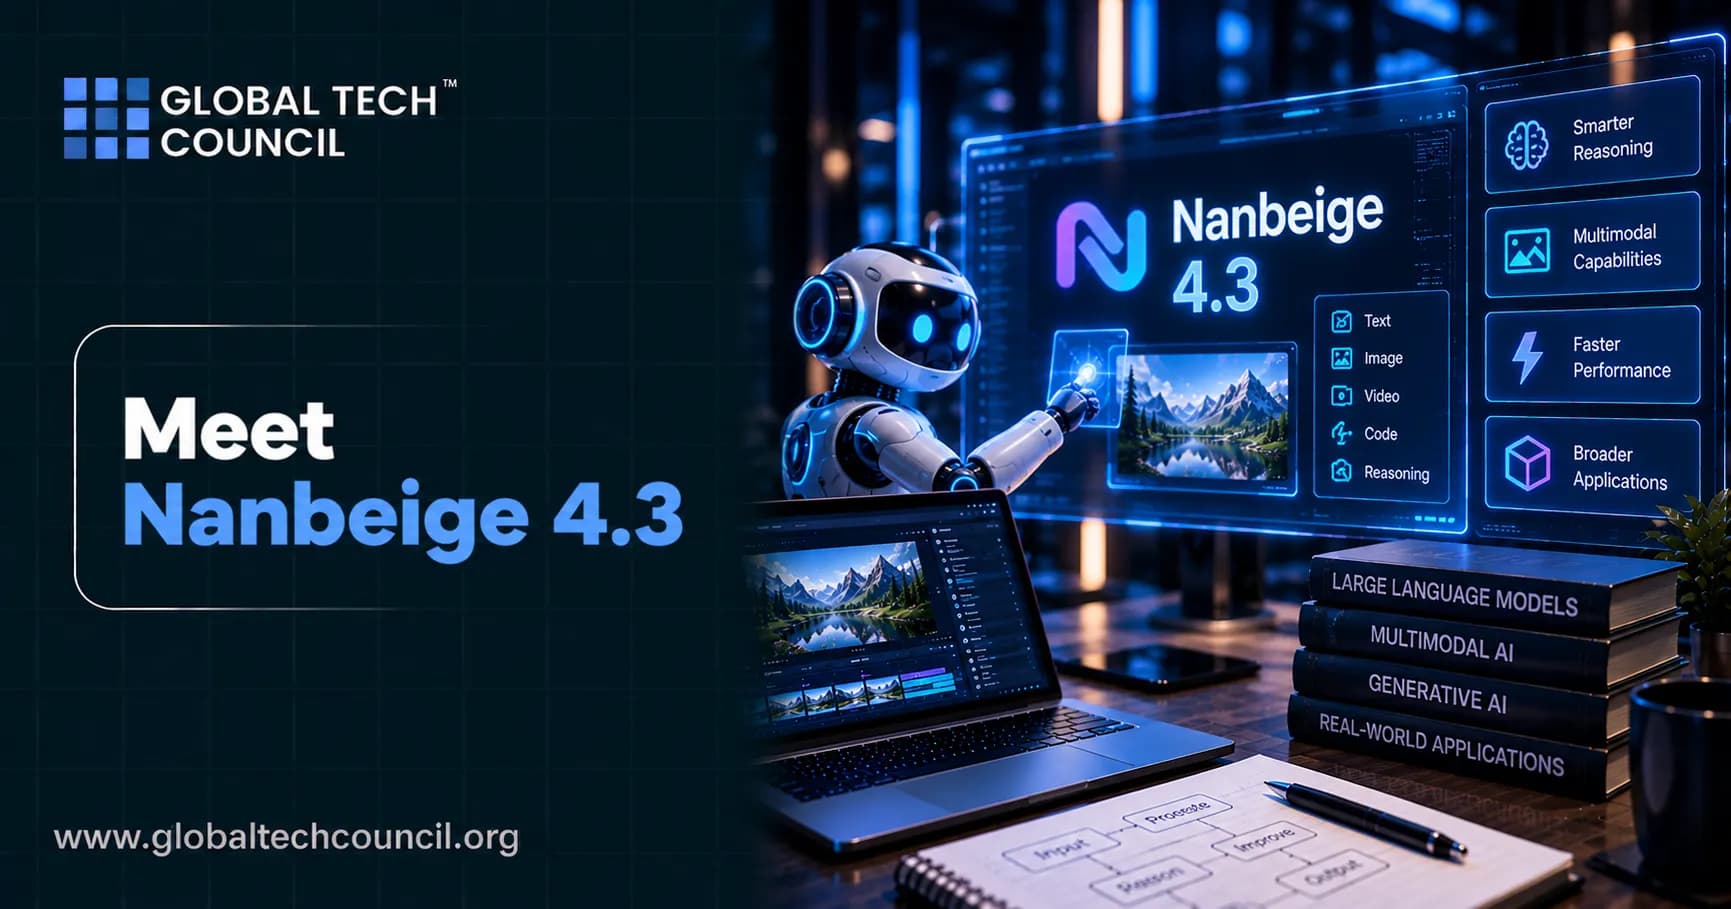
Imagine an AI helper that does not just chat, but opens a terminal, reads a messy codebase, runs commands, checks the results, and keeps going until the job is done. That is the idea behind Nanbeige 4.3, a new open-source AI model released on Hugging Face on 24 October 2026. It has about 33 billion parameters, a very long memory, and a business-friendly license. You can download it, run it on your own servers, and build on it. Because releases like this change what AI can do at work, many professionals begin with a foundation course like the Certified Artificial Intelligence (AI) Expert credential. This guide introduces Nanbeige 4.3 in plain language, explains how it performs, and points out what to check before you rely on it.
Meet Nanbeige 4.3 in Plain English
Nanbeige 4.3 belongs to the open-weight family of language models. A language model is a program that learned from enormous collections of writing, which lets it follow instructions, compose answers, and produce code. Its official name is Nanbeige4.3-33B, and the number tells you its size.
The One-Line Answer
Nanbeige 4.3 is a free-to-download, text-only AI model for English and Chinese that is designed for agent tasks such as coding, tool use, and multi-step office work.
Who Built It
The model comes from Nanbeige LLM Lab, which is the language model research team inside BOSS Zhipin, a Chinese job platform. The contact address on the model card uses the platform’s parent domain, kanzhun.com. Earlier Nanbeige releases were mostly small models of around 3 billion parameters, so this launch is a big step up in size.
Four Terms Made Simple
Parameters: the adjustable numbers inside a model. More parameters usually means more capacity to learn.
Context window: how much text the model can keep in view at once. Nanbeige 4.3 lists 524,288 tokens, often shortened to 512K.
Open-weight: the trained model files are public, so anyone can download them.
Agentic: able to plan steps, use tools, and act on results instead of answering one question at a time.
Why Nanbeige 4.3 Stands Out
Many open models compete on chat quality. Nanbeige 4.3 competes on getting work done. As more teams use generative tools to write code, draft content, and automate routine tasks, learners who want to see how these systems are built and checked often turn to the Certified Generative AI Expert program.
Built to Act, Not Just Talk
The lab focuses on agent work: running terminal commands, fixing software issues, calling tools, and finishing long tasks. The model card describes strong performance for open models in the roughly 30 billion parameter class.
A Teacher Model With a Plan
The lab calls Nanbeige 4.3 its flagship teacher. The strategy is to build one large, capable agent first and then pass its skills to smaller models through distillation. A smaller Nanbeige4.3-3B has been teased as the first student, though no release date was given. Think of a master craftsperson training an apprentice. The apprentice can later work in places where the master is too large to fit.
A Memory Big Enough for Large Projects
A 512K context window can hold a sizable codebase, a long contract set, or many pages of notes. The model is also trained to keep its earlier reasoning across turns when a setting called preserve_thinking is turned on, which the lab recommends for tool use and coding agents.
A License Businesses Can Work With
The license is Apache 2.0, which allows commercial use, modification, and redistribution of the weights. Have someone read the full text before you ship a product that depends on it.
Inside the Model: Specs for the Curious
Developer: Nanbeige LLM Lab (BOSS Zhipin)
Released: 24 October 2026 as an Instruct model plus a Base model
Architecture: dense, Llama-style, with no mixture-of-experts
Size: about 33.1 billion parameters across 52 layers
Languages: English and Chinese
Input: text only
Context: 524,288 tokens
License: Apache 2.0
Weights: roughly 66 GB when stored in BF16
Dense Versus Mixture-of-Experts
In a dense model, every parameter works on every token. Mixture-of-experts models wake up only a slice of themselves each time, which can be cheaper to run. The lab chose dense, and one analysis suggests that suits a teacher role, because uniform weights may transfer more neatly into a dense student. The trade-off is higher serving cost per token.
Thinking Controls
The model reasons step by step by default, and you can turn that off. The lab’s advice for agent and tool jobs is a temperature of 1.0 and a top-p of 0.95, capped at 65,536 new tokens. Reasoning and chat do better at a temperature of 0.6, capped at 262,144.
How Well Does Nanbeige 4.3 Perform?
Every score below was published by the lab. Independent groups had not yet reproduced them in the first days after launch, so read the numbers as promising claims rather than final rankings.
The Rivals It Is Measured Against
The lab compares Nanbeige 4.3 with three other open models in the 27 to 31 billion parameter range: Qwen3.8-27B, Muse-Glimmer-30B, and Gemma4-31B. All were tested at their highest thinking effort. Qwen3.8-27B is the closest competitor in most rows, while Muse-Glimmer-30B and Gemma4-31B trail it on many agent tests. Keeping the comparison group in the same size class makes the contest fairer, but it also means the results say nothing about much larger models.
Coding and Terminal Work
Against Qwen3.8-27B, a rival open model, the lab reports 80.9 versus 73.0 on Terminal-Bench 2.1 and 23.8 versus 6.3 on the harder Terminal-Bench 4. On DeepSWE it reports 65.5 versus 42.5. On SWE-Atlas-QnA, which tests questions about code, the figures are 50.8 versus 41.9.
Office and Business Tasks
On Automation Bench the lab reports 54.2 against 38.3. On DeepPlanning it reports 63.3 against 49.2, and on Claw-Eval it reports 78.3 against 75.2. A simulated business test called YC-bench pays out $1,025,437 against $641,290.
Where Rivals Still Lead
The lab’s own table shows Qwen3.8-27B edging ahead on two rows: SWE-Bench Pro (61.7 against 60.3) and GDPval (86.4 against 84.8). Gemma4-31B leads on GPQA Diamond with 91.3. On several rows, such as Tau3-Bench at 48.8 versus 48.5, the models are almost tied. Reports differ on the exact tally of wins, with counts of 17 and 18 out of 20 both appearing, so treat any single number loosely.
The Base Model
The Base version, meant for custom training, is compared with Gemma4-31B-Base. It scores 66.9 versus 59.3 on MMLU-Pro and 62.0 versus 41.5 on GPQA, according to the model page.
Why These Numbers Need Care
Several tests were adapted. Automation Bench used 600 public tasks, Claw-Eval used a 157-task subset, and YC-bench kept only the ten latest user turns. Runs also used preserve_thinking, and some used Claude Code as a harness. One review notes that the results are not directly comparable to public leaderboards, and it also points to mismatches between the lab’s tables and the official figures for some rivals.
How to Get Started With Nanbeige 4.3
Using a model of this size involves servers, GPUs, and careful memory planning. Learning how emerging systems fit together is easier with a wide view of modern infrastructure, and a Deep Tech Certification is one way to explore that bigger picture.
Step One: Read the Model Card
Find the Nanbeige organization on Hugging Face and read the model card for the Instruct and Base versions. Confirm the context length, license, and recommended settings there.
Step Two: Plan Your Hardware
The BF16 weights take about 66 GB. Long context adds a KV cache of roughly 208 KiB per token, which one analysis converts to around 104 GiB for a single full 512K sequence. In practice, many teams will cap the context or compress the cache. The lab’s serving examples split the work over four GPUs, a method called four-way tensor parallelism.
Step Three: Choose a Runtime
The model works with Hugging Face Transformers, vLLM, and SGLang. Transformers needs the trust_remote_code option. The vLLM and SGLang recipes reuse Qwen3 style reasoning and tool parsers, which suggests the model can slot into tooling already built for Qwen. Tool calls are recommended in XML format, and JSON is also supported.
Step Four: Consider Community Builds
Soon after launch, community members uploaded smaller builds in formats such as GGUF, FP8, NVFP4, and EXL3. These can cut memory use, though their effect on accuracy is not documented, so test them on your own tasks.
Step Five: Expect to Self-Host
At capture time no hosted inference provider was serving the model, so access means running it yourself or waiting for a provider to add it.
A Simple Way to Run Your First Test
Pick three small jobs from your own work, such as fixing a short bug, summarizing a long document, and drafting a script. Run them with the thinking mode on, then repeat them with your current model using the same prompts. Compare the answers, the time taken, and the memory used. A short, honest trial like this tells you more than any chart.
What Can You Build With Nanbeige 4.3?
Coding Assistants
Terminal-heavy coding agents are the clearest fit. The model can read a repository, run tests, and revise its work across many turns.
Workflow Automation
Tool calling and long context suit tasks such as processing reports, filling structured forms, and moving data between systems.
Domain Specialists
The Base model invites custom post-training, and the lab has said it welcomes industry collaboration. A company could train a version tuned to its own field.
Research on Agent Training
Because the weights are public, researchers can study how a teacher model behaves and prepare for the promised student release.
Open-Weight Is Not the Same as Fully Open
Nanbeige 4.3 shares its trained weights, but not everything behind them. Training data, the data mixture, training code, token counts, and the post-training recipe were not published. No technical report was available at the time of early coverage, and there were no published safety evaluations or speed measurements. That makes careful testing even more important.
Things to Weigh Before You Adopt
Self-reported results: run your own tests on your own tasks.
Memory demands: using the full context calls for server-grade hardware.
Text only: images and audio cannot be given to it.
Two languages: the supported languages are English and Chinese.
Dense cost: every parameter is active for every token.
Early ecosystem: community tools and reviews are still catching up.
Where Nanbeige 4.3 Fits in the Open Model Race
Open models have been closing the gap with closed systems, and releases like this one show how fast the middle of the market is moving. Nanbeige 4.3 sits in a crowded group of capable models around 30 billion parameters. Its edge is a focus on agent work, a very long native context, and an Apache 2.0 license. Its use of familiar Qwen style tool parsers may also make it easier to try inside existing setups. Whether it keeps that edge will depend on independent testing and on the arrival of the smaller student model.
Why Human Judgment Still Counts
Models change quickly, but good judgment lasts. Being able to question a benchmark, spot an adapted test, and match a tool to a real job is valuable in almost any role.
As artificial intelligence becomes part of everyday business operations, employers increasingly need people who can apply AI knowledge responsibly and effectively. Evaluating candidates on relevant skills, reasoning, and practical understanding can support stronger hiring decisions. HireValid can be explored by organisations seeking structured candidate assessments.
Final Thoughts on Nanbeige 4.3
Nanbeige 4.3 is a notable open model because it aims at real work, supports a huge context window, ships under a permissive license, and comes with a clear plan to teach smaller models. It also comes with caveats worth remembering: scores that nobody has checked yet, a large appetite for memory, and a student model still on the way.
When you pass news like this to customers or colleagues, how you explain it matters as much as the technology itself. A Marketing Certification can help you turn technical updates into messages people trust. Open the model card, run Nanbeige 4.3 on a task that matters to you, and let your own results guide you.
FAQs
1. What is Nanbeige 4.3?
Nanbeige 4.3 is an AI model series developed by Nanbeige LLM Lab, designed for advanced reasoning, coding, tool use, and agentic workflows. Its flagship model, Nanbeige4.3-33B, targets complex tasks that require multiple steps rather than simple text generation.
2. What makes Nanbeige 4.3 different from other AI models?
Nanbeige 4.3 emphasizes agentic capabilities, including tool calling, multistep problem-solving, and coding workflows. Its large context window also helps it process lengthy documents and codebases, making it useful for certain complex professional tasks.
3. Is Nanbeige 4.3 an open-source AI model?
Nanbeige4.3-33B is released as an open-weight model under the Apache 2.0 license. This allows developers to access, modify, and deploy the model subject to the license terms. As with other open-weight models, users should distinguish access to model weights from access to every component of the original training process.
4. What are the key features of Nanbeige 4.3?
Key features include coding assistance, tool calling, agentic task execution, configurable reasoning, and support for long-context processing. The model is designed to support workflows that involve analyzing information, selecting actions, and using external tools to complete tasks.
5. How large is the Nanbeige4.3-33B model?
Nanbeige4.3-33B contains approximately 33 billion parameters. Its size enables substantial language-model capabilities, but running it efficiently requires appropriate computing resources, particularly when processing long contexts or serving multiple users.
6. What is the context window of Nanbeige 4.3?
Nanbeige4.3-33B supports a context window of up to 512K tokens. This can help it process large documents, extensive codebases, and long task histories, although actual memory consumption and performance depend on the inference configuration.
7. Can Nanbeige 4.3 help developers write code?
Yes. Nanbeige 4.3 is designed to support code generation, debugging, code analysis, and multistep software-development workflows. Developers should still run tests, review generated code, and verify security-sensitive changes before using them in production.
8. Does Nanbeige 4.3 support AI agents?
Yes. The model is designed to support agentic workflows by combining reasoning with tool calling and iterative task execution. When integrated into an agent framework, it can help automate coding tasks, retrieve information, and interact with external systems within defined permissions.
9. Can Nanbeige 4.3 automate office tasks?
Nanbeige 4.3 can assist with tasks such as document analysis, research, report preparation, information organization, and workflow coordination. The extent of automation depends on the tools and integrations available to the application.
10. How can developers run Nanbeige 4.3 locally?
Developers can download the model weights and use compatible inference frameworks, such as Transformers, vLLM, or SGLang. A successful deployment requires compatible software, sufficient memory, and suitable hardware. The model's official configuration instructions should be followed for the selected version.
11. What hardware is required to run Nanbeige 4.3?
Hardware requirements depend on model precision, context length, and workload. The full-precision BF16 weights alone require roughly 66 GB of memory, with additional memory needed for inference and context processing. Quantization can reduce memory requirements but may affect performance.
12. What is the difference between Nanbeige4.3-33B and Nanbeige4.3-33B-Base?
Nanbeige4.3-33B is the instruction-tuned model intended for general use and agentic tasks. Nanbeige4.3-33B-Base is a base model intended for developers and researchers who want to conduct additional training or customize the model for specialized applications.
13. How does Nanbeige 4.3 perform on coding benchmarks?
The development team's published evaluations report competitive results on agentic coding benchmarks, including Terminal-Bench 2.1 and DeepSWE. However, benchmark scores depend on the evaluation setup and should be treated as reported results until independently replicated.
14. Can Nanbeige 4.3 compete with other open-weight AI models?
Nanbeige 4.3 is designed to compete in areas such as coding, reasoning, and agentic task execution. Its practical performance relative to other models depends on the specific task, hardware, quantization, prompting strategy, and evaluation methodology.
15. What is knowledge distillation in the Nanbeige 4.3 ecosystem?
Knowledge distillation transfers useful capabilities from a larger teacher model to a smaller student model. The Nanbeige team's development strategy includes using the 33B model as a teacher to help create smaller models that are more efficient to deploy.
16. Is Nanbeige 4.3 suitable for small businesses?
It may be suitable for small businesses that need customized AI workflows and have access to appropriate computing resources or hosted inference services. Businesses should assess deployment costs, privacy requirements, performance, maintenance, and integration needs before adopting it.
17. What are the limitations of Nanbeige 4.3?
Potential limitations include high hardware requirements, incorrect outputs, inconsistent tool use, and performance variations across tasks. Long-context support does not guarantee that every detail will be understood accurately, so important results should be validated.
18. Is Nanbeige 4.3 safe for commercial applications?
Commercial use is generally permitted under the Apache 2.0 license, subject to its terms and applicable laws. Organizations should also review model-specific notices, security requirements, data-handling practices, and the risks associated with connecting the model to business systems.
19. Who should use Nanbeige 4.3?
Software developers, AI researchers, enterprise automation teams, and organizations experimenting with open-weight AI may benefit from evaluating Nanbeige 4.3. It is especially relevant to teams interested in coding agents, tool-enabled workflows, and long-context tasks.
20. What does Nanbeige 4.3 mean for the future of AI?
Nanbeige 4.3 reflects the growing focus on AI systems that can use tools and complete multistep tasks rather than merely generate responses. Its approach to open-weight deployment and model distillation may help expand access to agentic AI, provided that efficiency, reliability, and security continue to improve.
Related Articles
View All
AI & ML
Meet NullMotion: The New Open-Source Tool
NullMotion is a free, open-source tool that plays a finished motion-graphics ad above the rough drafts it grew from, keeps them frame-synced, and exports the breakdown as one MP4. Learn how it works, how to run it, and who it suits.
AI & ML
Meet GPT-6.1 Terra: OpenAI’s New AI Model
OpenAI has introduced GPT-6.1 Terra, a mid-sized model with stronger computer use, better image reading and a 50% lower API price. Learn what it does, how it performs, and who should use it.
AI & ML
Meet Gemini 4 Argon: Google’s New AI Model
Google has launched Gemini 4 Argon, a new AI model built for deep, multi-step work in coding, science, law, finance and security. Learn its features, pricing and how to access it.
Trending Articles
The Role of Blockchain in Ethical AI Development
How blockchain technology is being used to promote transparency and accountability in artificial intelligence systems.
AWS Career Roadmap
A step-by-step guide to building a successful career in Amazon Web Services cloud computing.
Top 5 DeFi Platforms
Explore the leading decentralized finance platforms and what makes each one unique in the evolving DeFi landscape.