
Cross Validation Explained: Estimating Model Performance Reliably
Cross validation explained for reliable model evaluation, including k-fold, nested cross validation, leakage risks, metrics, and when simpler methods are enough.


344 articles published
Cross validation explained for reliable model evaluation, including k-fold, nested cross validation, leakage risks, metrics, and when simpler methods are enough.

Learn how to diagnose overfitting vs underfitting using validation metrics, learning curves, and cross validation, then apply targeted fixes.

Learn how model evaluation metrics such as accuracy, precision, recall, F1 score, ROC AUC, and PR AUC guide better machine learning decisions.
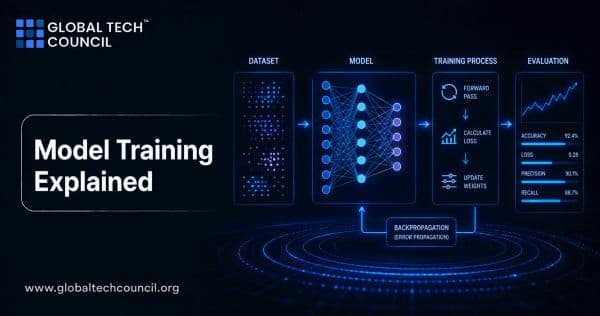
Learn what model training is, how the core learning loop works, and how loss functions, backpropagation, gradient descent, data splitting, regularization, and optimization help build reliable machine learning models.

Learn how data preprocessing for machine learning improves model accuracy, reliability, and governance through cleaning, scaling, encoding, and transformation.

Feature selection helps ML models use the right inputs, reduce noise, improve speed, and support explainability without leaking test data.

Learn practical feature engineering in machine learning, including encoding, scaling, missing values, temporal features, selection, and leakage control.

Learn deep learning fundamentals, including neural networks, backpropagation, loss functions, CNNs, transformers, regularization, deployment, and ethics.

Neural networks explained through their structure, training workflow, key architectures, practical trade-offs, and real-world AI applications.

XGBoost explained for practitioners: learn why gradient boosted trees still dominate tabular machine learning competitions and enterprise prediction tasks.

Gradient boosting explained for practitioners: learn how boosted trees work, when to use XGBoost, LightGBM, or CatBoost, and how to tune models safely.

Learn how K-Means clustering finds groups in unlabeled data, how to choose k, preprocess features, evaluate clusters, and avoid common production mistakes.